
In June 2015 we published on this very blog how to get started with Big Data and Business Analytics. The premise was simple: stop deciding by intuition and start measuring KPIs. Ten years later, the problem is not a lack of data —it is the excess— and the solution no longer rests on dashboards alone, but on autonomous AI agents that reason, act and approve decisions in milliseconds. That, in one sentence, is the promise of Agentic Analytics 2025.
At BAOSS we have guided more than 40 organizations through 2024-2025 in the transition from descriptive analytics to autonomous decision intelligence. The patterns repeat themselves: data fragmented across 12+ sources, data teams saturated with ad-hoc requests, and executives still asking for “the usual Excel file” while competitors deploy agents that negotiate prices, detect fraud in real time and reallocate marketing budget every hour. Before scaling, it is worth reading whether your company is exposed to the disruption shock and how to control what you already have deployed.
The real 2025-2026 problem: abundant data, slow decisions
According to Databricks’ State of Data & AI 2025, 78% of Spanish companies claim to have “enough data”, but only 23% manage to turn insights into operational action in less than 24 hours. The bottleneck is no longer ingestion —Kafka, Fivetran, Airbyte and CDC solve that— but the last mile: from insight to execution without human friction.
The symptoms we see in initial audits:
- Decision-action latency: 3-14 days from when an analyst detects an anomaly until operations executes the fix.
- Analytical shadow IT: 40-60% of ML models live in local notebooks, with no versioning, monitoring or data lineage.
- Hidden opportunity cost: Data science teams spending 65% of their time on cleaning and repetitive feature engineering (source: internal BAOSS survey, n=34 clients, 2024).
- Reactive governance: Privacy and security policies applied a posteriori, after incidents or external audits.
The paradigm shift: Agentic Analytics 2025
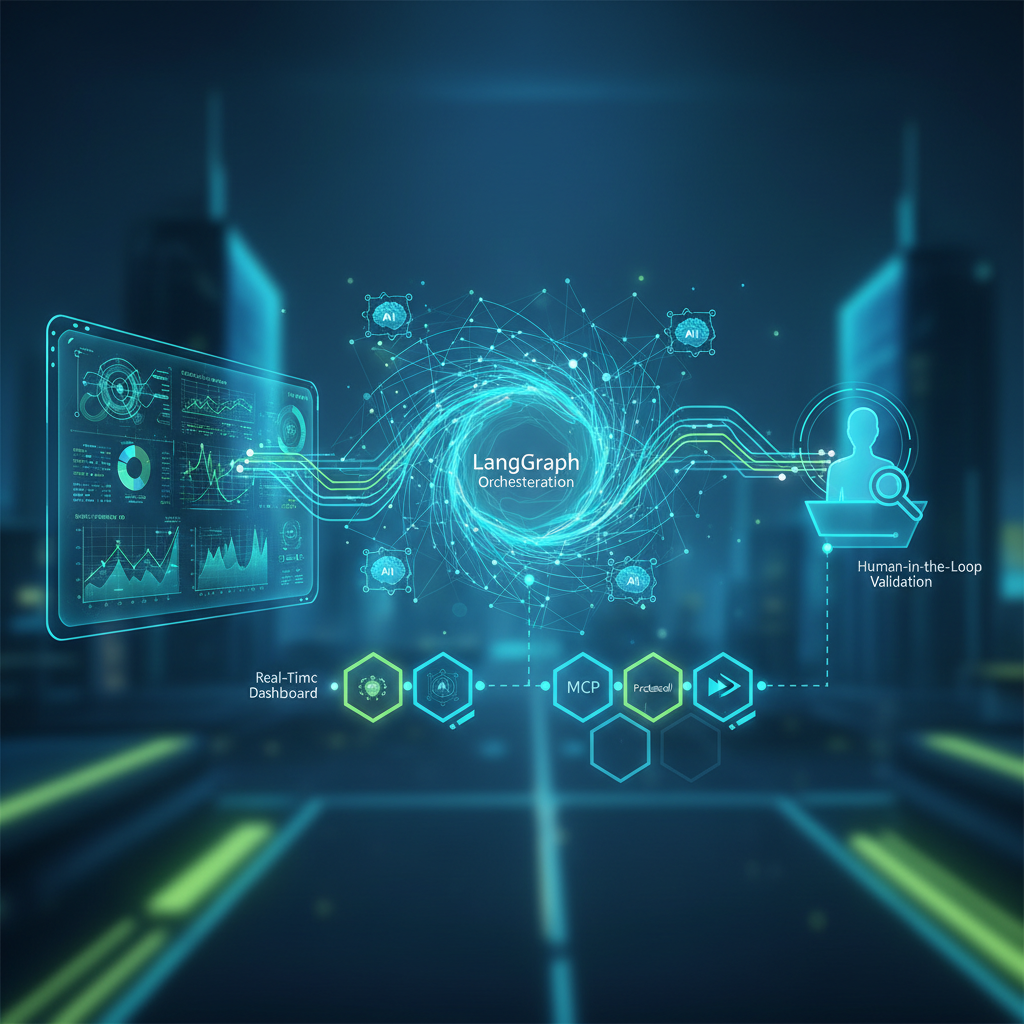
Analytics in 2025 is not “better dashboards”. It is multi-agent systems that perceive, reason and act on your business data with configurable human oversight. The reference architecture we deploy at BAOSS combines:
- Knowledge layer (RAG + GraphRAG): Vector indexes (pgvector, Qdrant, Weaviate) + knowledge graphs (Neo4j, Kuzu) for semantic context and traceability. Agents ask “what does this KPI mean?” and get the definition, lineage, owner and documented exceptions.
- Agent orchestration (LangGraph, CrewAI, AutoGen): Deterministic workflows with human-in-the-loop at critical steps. Example: detector agent → validator agent (business context) → executor agent (ERP/CRM API) → auditor agent (immutable log).
- Base and local models: GPT-4o / Claude 4 for complex reasoning and SQL/Python code generation; vLLM + Ollama serving Llama-3.1-70B, Qwen2.5-Coder or Nemotron-3-Ultra on your own GPU for sensitive data, latency <100ms and fixed cost.
- MCP protocol (Model Context Protocol): An open standard (Anthropic, 2024) that lets agents discover and consume tools (SQL queries, API calls, sending emails, triggering CI/CD) without hardcoding integrations. Each data source exposes an
mcp.jsonwith schemas, permissions and examples. - Native observability: Langfuse, Arize Phoenix or Weave for full traces: prompt → retrieval → tool calls → response → human feedback. Metrics: p95 latency, escalation-to-human rate, accuracy vs ground truth.
BAOSS cases 2024-2025 (anonymized, real metrics)
Case 1: Omnichannel retail — Autonomous repricing with guardrails
Context: 1,200 SKUs, 45 physical stores + e-commerce, competitors monitored every 15 min. Pricing team: 3 analysts.
Deployed solution (8 weeks): A PriceWatcher agent (LangGraph + GPT-4o) that ingests competitor prices, historical elasticity, stock, seasonality and legal rules (food chain law, minimum margins). It proposes daily adjustments; a validator agent checks business rules; a human approves the batch in 5 min via Slack/Teams. Deployed on on-premise Kubernetes (A100 GPU) with vLLM serving Llama-3.1-70B-Instruct for local explainability.
Results at 6 months:
- +12.3% gross margin in piloted categories (vs control).
- 87% reduction in analyst time on operational pricing (from 18h/week to 2.3h/week).
- ROI 3.8x (total project cost: €180k; attributable EBITDA increase: €680k).
- Zero legal incidents; full traceability for CNMC audit.
Case 2: Mid-tier banking — Fraud detection in instant payments (SEPA Inst)
Context: 2.4M transactions/day, maximum latency 800ms (EBA rule). Legacy system based on static rules (FICO) with 2.1% false positives and 0.34% undetected fraud.
Solution: Streaming pipeline (Redpanda + Flink) → feature store (Feast) → XGBoost + TabNet ensemble (trained on 36 months of history) → explainer agent (Claude 4 via Bedrock) generates a natural-language narrative for the SOC analyst. An AutoBlock agent (AutoGen) executes reversible blocking + customer notification + CRM case. All orchestrated with LangGraph, human-in-the-loop only for scores 0.65-0.85.
Results at 4 months:
- False positives: 2.1% → 0.47% (-78%).
- Fraud detected: +41% (incremental recovery of €2.3M/year).
- p99 latency: 340ms (within SLA).
- SOC analyst time per case: 12 min → 2 min (agent self-documentation).
Case 3: Last-mile logistics — Route planning with collaborative agents
Context: 3,200 couriers, 180,000 deliveries/day, 2h commitment window. The classic optimizer (OR-Tools) recalculates every 30 min; it does not factor in real-time traffic, weather incidents, driver preferences or dynamic vehicle load.
Solution: CrewAI multi-agent system: DataIngestor (traffic APIs, AEMET, fleet telemetry) → RoutePlanner (heuristics + fine-tuned RL) → DriverMatcher (preferences, remaining hours, ADR certification) → Dispatcher (driver app push + confirmation). Shared context via an internal MCP server. Local models (Qwen2.5-32B-Coder on vLLM) for generating complex SQL constraints.
Results at 3 months:
- Km/delivery: -14.2% (€1.1M/year saved in fuel + maintenance).
- Deliveries within window: 89% → 96.7%.
- Driver satisfaction (eNPS): +23 pts (perceived autonomy).
- Progressive rollout: 2 pilot hubs → 12 hubs in 10 weeks.
Step-by-step guide: Your Agentic Analytics plan 2025-2026
1. “Agent-Ready” maturity diagnostic (Weeks 1-2)
Don’t buy tools; audit execution capability. We assess 5 dimensions:
- Data Contracts: Do you have versioned schemas (Protobuf/Avro), clear owners, freshness SLAs per domain?
- Feature Store & Semantic Layer: Are metrics and features defined once and consumed by BI, ML and agents? (dbt + Cube / dbt Semantic Layer).
- GPU/CPU infrastructure: Capacity to serve local models (vLLM/Ollama) or 100% cloud dependency? Cost/latency/privacy.
- Governance & Privacy by Design: Catalog of sensitive data (PII, financial, health)? Role + purpose-based access policies (OPA/Cedar)? Up-to-date DPIA?
- “Human-in-the-loop” culture: Are operations teams willing to validate agent decisions? Training in prompt engineering and output evaluation?
Deliverable: Agent Readiness Scorecard + 3 quick wins prioritized by impact/effort/risk.
2. Pick the first “Agent-First” use case (Week 3)
BAOSS criteria for the pilot:
- Recurrent, high-frequency decision (daily/hourly), today manual or semi-automated.
- Rich, documentable context (business rules, exceptions, decision history).
- Clear, measurable success metric within 8-12 weeks (margin, time, NPS, risk).
- Native reversibility: the agent proposes, the human disposes; rollback in under 1 click.
- Data accessible via API/SQL with no prior mass migrations.
Ideal examples: inventory replenishment, lead prioritization, accounting reconciliation, shift assignment, supplier invoice validation.
3. “Starter Kit” reference architecture (Weeks 4-6)
We deploy an operable foundation in your environment (cloud/on-prem/hybrid) in 3 weeks:
- Data Platform: Kafka/Flink (streaming) + Iceberg/Delta Lake (lakehouse) + dbt (transformation) + Feast (feature store).
- Knowledge Layer: Vector DB (Qdrant/Weaviate) + Graph DB (Neo4j) + MCP servers per domain (Postgres, S3, ERP, CRM, GitHub, Slack).
- Agent Runtime: LangGraph (production) + vLLM/Ollama (local models) + API keys for GPT-4o/Claude 4 (complex reasoning).
- Observability: Langfuse + OpenTelemetry → Grafana (latency, cost, escalations, accuracy).
- Governance: OPA/Cedar (policies), Unity Catalog/Ranger (RBAC), MLflow/LangSmith (model/prompt versioning).
Typical starter kit investment: €60-90k (infrastructure + 2 BAOSS consultants). Deployment via IaC (Terraform + Helm), reproducible and versioned.
4. End-to-end pilot: from data to autonomous decision (Weeks 7-10)
- Week 7: Pilot data ingestion → feature store → semantic layer. Data Contracts validation.
- Week 8: Detector + validator agent development (LangGraph). Unit tests + shadow mode (the agent proposes, does not execute).
- Week 9: Human-in-the-loop in staging: operations validate 50+ decisions; measuring accuracy, false positives, review time.
- Week 10: Controlled go-live: the agent executes with guardrails (amount limits, risk thresholds, human approver). Real-time dashboard.
Deliverable: Pilot report with audited metrics (ROI, latency, accuracy, adoption) + scaling plan.
5. Scaling and the agent factory (Week 11+)
- Agent Factory: Reusable LangGraph templates (detector, validator, executor, auditor) + CI/CD for agents (tests, RAGAS/DeepEval evals, canary deploy).
- Internal MCP catalog: 1 MCP server per source system; new agents consume tools with no ad-hoc development.
- Agentic center of excellence: 2-3 internal profiles (Data Engineer + ML Engineer + Business Analyst) trained by BAOSS; progressive autonomy.
- Continuous governance: Quarterly reviews: model drift, RAG faithfulness, token cost, AI Act/ISO 42001 compliance.
2025-2026 tech stack: What we deploy in production
| Layer | BAOSS pick | Why |
|---|---|---|
| Streaming / Ingestion | Kafka / Redpanda + Flink SQL | Exactly-once, streaming SQL, sub-second, self-operated or managed |
| Lakehouse / Storage | Iceberg + Trino/StarRocks / Snowflake / Databricks | ACID, time-travel, concurrent reads, open format |
| Transformation / Semantic Layer | dbt Core + dbt Semantic Layer / Cube | Metrics defined once, consumed by BI, ML, agents |
| Feature Store | Feast (open source) / Tecton (managed) | Consistent online/offline features, point-in-time correctness |
| Vector DB / Graph DB | Qdrant / Weaviate / pgvector + Neo4j / Kuzu | Hybrid search, GraphRAG, multi-tenancy, metadata filtering |
| Agent Orchestration | LangGraph (stateful, HIL, checkpointing) | Robust production, cycles, time-travel debugging, native OpenTelemetry |
| LLM Serving | vLLM (PagedAttention, tensor parallel) + Ollama (edge) | 2-4x HF throughput, OpenAI API compatible, AWQ/GPTQ 4-bit |
| Base Models | GPT-4o / Claude 4 (API) · Llama-3.1-70B/405B · Qwen2.5-Coder · Nemotron-3-Ultra (local) | API: speed, multimodal. Local: sovereignty, deterministic latency, fixed cost |
| Connectors / Tools | MCP (Model Context Protocol) + own servers | Open standard, decouples agent from source, 50+ ready-made servers |
| Observability / Eval | Langfuse + OpenTelemetry + Grafana + RAGAS / DeepEval in CI/CD | Full traces, executive dashboards, automatic quality gates |
| Governance / Security | OPA/Cedar + Unity Catalog/Ranger + MLflow/LangSmith + Vault/External Secrets | Policies as code, RBAC, lineage, rotated secrets, AI Act ready |
| Infra / Deployment | Kubernetes (EKS/GKE/AKS/on-prem) + Terraform + Helm + ArgoCD | GitOps, reproducible, multi-cloud, automatic scaling |
Real risks and how we mitigate them
- “Hallucination in a critical decision” → BAOSS fix: mandatory grounding (source citation), human-in-the-loop at mid scores, tool calling to systems of record (ERP/CRM) for real-time verification, continuous RAGAS/DeepEval evals with a faithfulness ≥ 0.85 threshold.
- “Silent data/feature drift” → Fix: Statistical monitors in the feature store (PSI, KS-test, missing rate) + Grafana alerts + automatic weekly retraining if drift exceeds the threshold.
- “Runaway token cost” → Fix: Prompt caching (Bedrock/Vertex), local models (vLLM/Ollama) for repetitive tasks (classification, extraction, SQL generation), intelligent routing by complexity, monthly budget per agent with a hard stop.
- “Operational resistance / lack of trust” → Fix: Data Champions program (1 profile per domain), mandatory 2-week shadow mode, native explainability (the agent justifies every decision with a citation), shared metrics (accuracy vs human).
- “Cloud/LLM vendor lock-in” → Fix: MCP-first architecture (decoupled tools), open models as default (Llama/Qwen/Nemotron), standard APIs (OpenAI-compatible), portable IaC (Terraform + Helm).
Conclusion: you don’t need “more data”, you need “better autonomous decisions”
The Big Data of 2015 promised that more data would bring better decisions. In 2025 we know that data is a commodity; the competitive advantage lies in the decision architecture: agents that reason over your business context, execute with guardrails, learn from human feedback and leave a complete audit trail.
The organizations that win in 2025-2026 will not be those with the biggest data lake, but those that have cut their decision-action latency from days to seconds with governance, explainability and measurable ROI.
At BAOSS we don’t sell dashboards; we design and implement Agentic Analytics that go from pilot to production in 10 weeks with audited metrics. If your analytics is still stuck in 2015, let’s talk.
Want to cut your decision-action latency from 14 days to 340ms with governed autonomous agents? Talk to our consulting team.
Prefer to talk to us directly? Contact the BAOSS team and tell us about your challenge.
Related articles: Why Big Data Makes Your Business Grow in 2026.