
What is Apache Hadoop? From the big data era to the AI lakehouse
In June 2015 we published on this very blog an introduction to Apache Hadoop. The title was simple: “What is Apache Hadoop?”. Ten years later, the question is no longer what Hadoop is, but how to move off it without stopping the business. Today the question is not just what Apache Hadoop is, but how to modernise into a lakehouse with AI without halting the business.
If you want to go further, we recommend reading AI agents: is your business exposed to the disruption shock? what is BAOSS, the operating system for business agents.
The ecosystem born to solve cheap massive storage and processing (HDFS + MapReduce) has become the number one bottleneck for organisations that want to run generative AI, autonomous agents and real-time data. At BAOSS we have guided six enterprise clients in 2026-2027 through full migrations from on-premise Hadoop 2.x/3.x clusters to open lakehouse architectures (Iceberg, Delta Lake, Hudi) on Kubernetes and hybrid cloud. The patterns repeat: runaway operating costs, 8-12 years of technical debt, and the inability to serve features to LLM models (GPT-4o, Claude 4, Llama 3.1 405B) with sub-second latency.
The real 2026 problem: what Apache Hadoop is and why to modernise the lakehouse for the era of AI agents
Hadoop’s original architecture assumes batch processing over immobile data. The 2026-2027 paradigm demands the opposite: data in motion feeding autonomous agents that reason, act and learn in closed loops (LangGraph, CrewAI, AutoGen, Semantic Kernel).
- Structural latency: the single NameNode (even with HA) and HDFS do not provide strong consistency with massive concurrent reads. RAG pipelines querying vector stores (pgvector, Milvus, Weaviate, Qdrant) need freshness in seconds, not hours of overnight ETL.
- Fragmented governance: Ranger + Atlas cover authorisation and basic lineage, but they do not solve versioned data contracts, automated quality gates (Great Expectations, Soda Core) or column-level end-to-end lineage down to the LLM prompt.
- Hidden maintenance cost: a 100-node on-premise cluster (typical Spanish enterprise) costs €1.2-1.8M/year between hardware, Cloudera/CDP licences, energy, cooling and 3-4 specialised FTEs. 68% of that spend is “keeping the lights on”, not innovation (Gartner 2024 data + BAOSS projects).
- Critical talent gap: MapReduce/Hive/Pig developers are a scarce and expensive profile. The new generation of data engineers works with dbt, SQLMesh, Dagster, Airflow 2.9+, Polars, DuckDB and LLM provider SDKs (OpenAI, Anthropic, Vertex AI, Bedrock, Ollama/vLLM for local inference).
A banking client (anonymised, 12 PB gross, 3 CDH 6.3 clusters) measured a 14-day lead time from the moment the business requested a new risk-scoring feature to when the data was available to the model. After modernisation: 4 hours via data contracts + CI/CD + feature store (Feast) + serving layer (Trino + Iceberg).
Target architecture 2026-2027: open lakehouse + native AI
There is no one-size-fits-all, but the winning pattern in our projects combines:
- Open table format: Apache Iceberg (highest enterprise adoption, native support in Trino, Spark, Flink, Dremio, Snowflake, BigQuery, Redshift). Delta Lake if the client is already on Databricks. Hudi for heavy streaming (massive CDC upserts).
- Federated query engine: Trino/Starburst as the single SQL layer for BI (Superset, Metabase, Power BI), data science (Jupyter, VS Code) and RAG retrieval (text-to-SQL with GPT-4o/Claude 4 → Trino → vector store).
- Unified catalog: Nessie (git-for-data), Polaris (incubating), Unity Catalog (opened in 2024) or Gravitino. It governs Iceberg/Delta/Hudi + schemas + tags + access policies in a single plane.
- Declarative orchestration: Dagster or Airflow 2.9+ with data assets and partitions defined as code. The spaghetti DAGs of 2015 disappear.
- Semantic layer + AI: Cube.dev or dbt Semantic Layer exposes certified metrics to agents (LangGraph tools, CrewAI tools, MCP servers). The LLM no longer hallucinates column names: it queries the semantic catalog via function calling.
This stack runs on Kubernetes (EKS, AKS, GKE, OpenShift, Rancher) with native operators (Strimzi for Kafka, Spark Operator, Trino Operator, Iceberg REST Catalog). The client chooses cloud, on-prem or hybrid with no format vendor lock-in.
Migration strategy: “Strangler Fig” by domains, not big bang
The classic mistake is trying to migrate the entire cluster at once. At BAOSS we apply the Strangler Fig pattern per data domain (Customer 360, Risk, Marketing, Supply Chain, Finance). Each domain follows 4 phases:
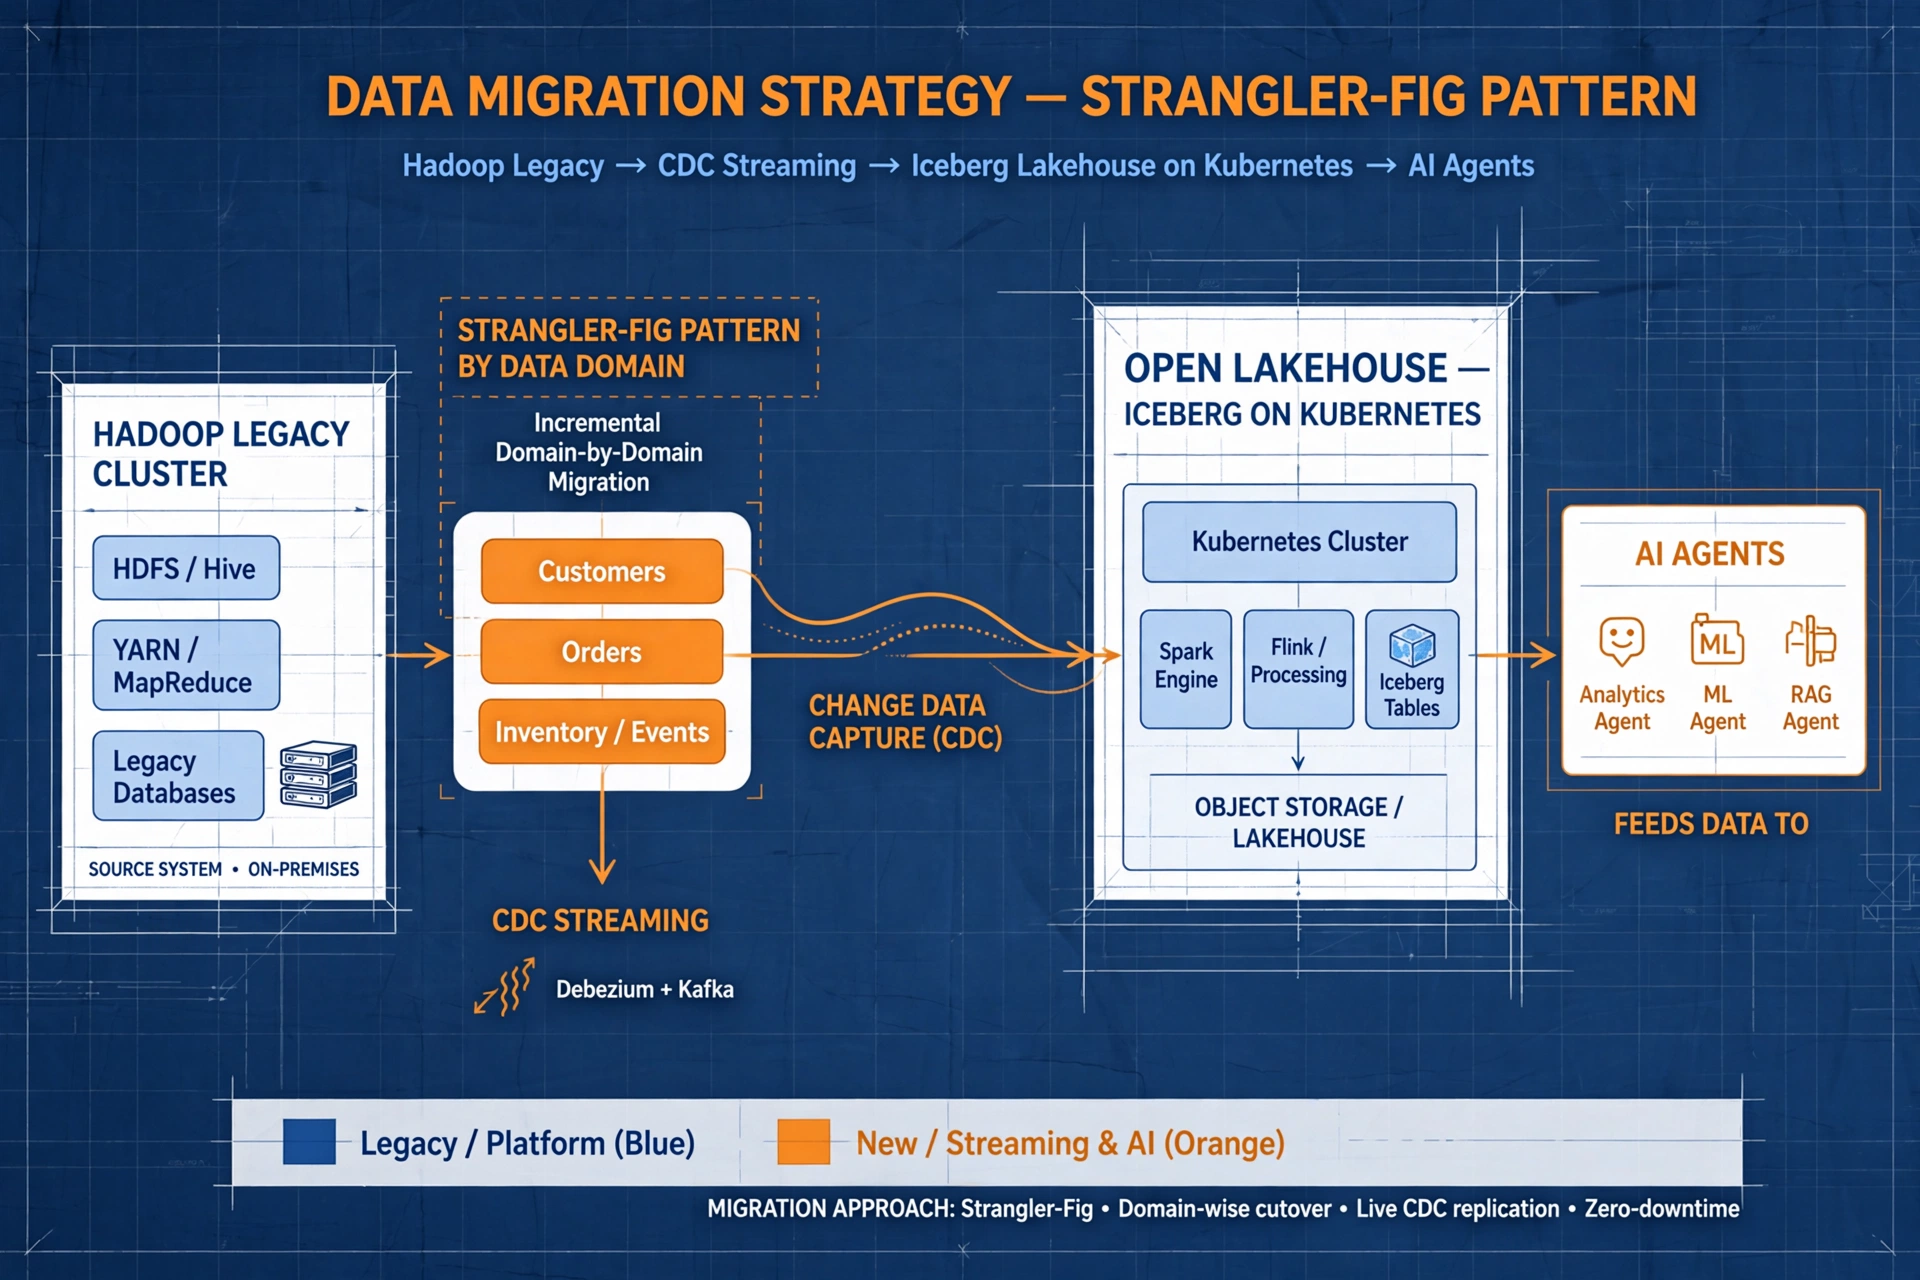
- Discovery & Contracting (2-3 weeks): automated profiling (DataHub + Great Expectations), definition of data contracts (Pydantic/Avro/Protobuf) agreed with consumers (data scientists, analysts, AI agents). Output: a catalog of versioned data products.
- Dual Write + Validation (4-6 weeks): CDC (Debezium + Kafka/Redpanda) replicates Hive/HBase changes → Iceberg in real time. Parallel pipelines (legacy + new) with automated data diff (data-diff, dbt-audit-helper). Exit metric: < 0.1% row/column discrepancy.
- Progressive cutover (2-3 weeks): feature flags in the consumption layer (Trino views, dbt models, API Gateway). Consumers migrate one by one. Instant rollback. Zero downtime.
- Decommissioning & Optimisation (ongoing): shutting down Hadoop nodes and freeing CAPEX/OPEX. FinOps: rightsizing Trino workers, compaction policies in Iceberg, partition pruning. Target: 40-55% reduction in total cost vs the Hadoop baseline.
Real case (retail, 8 PB, 450 TB/day of ingestion): the “Customer 360” domain was migrated in 11 weeks. ROI 3.2x at 6 months (savings in Cloudera licences + FTEs + time-to-insight). The “Supply Chain” domain is in progress, reusing 80% of the components (catalog, CDC, quality, orchestration).
The AI factor: why 2026 is the point of no return
The GenAI pilots of 2023-2024 (internal chatbots, document summarisation) have proven their value. The 2026-2027 wave is agentic AI in production: multi-agent systems that query data, execute actions (API, SQL, workflows) and close decision loops without a human in the loop (human-on-the-loop for critical validation).
Examples we are deploying at BAOSS clients:
- Financial reconciliation agent (LangGraph + Trino + Iceberg): receives bank statements in PDF/CSV → extracts transactions (GPT-4o vision) → matches them against the ledger (fuzzy SQL join) → proposes journal entries → a human validates → approves → posts. 87% reduction in manual time, 0 accounting errors in 3 months.
- Multi-warehouse stock optimisation agent (CrewAI + Flink + Iceberg + local vLLM/Llama 3.1 70B): predicts demand (forecasting model) → simulates redistribution (RL agent) → executes transfer orders (ERP API) → monitors stockout/overstock KPIs. ROI 4.1x in year 1.
- Enterprise RAG with governance (MCP server + Trino + pgvector + Unity Catalog): 12,000 technical documents + 400 Iceberg tables. The agent answers engineers’ queries with exact citations (table, column, row, document, page). 92% adoption by the engineering team in 8 weeks.
None of these cases works on legacy Hadoop. They require sub-second latency, versioned schemas, column-level lineage and open APIs (REST, GraphQL, MCP) so the agent can discover and consume data autonomously.
Recommended tech stack 2026-2027 (BAOSS version)
| Layer | Primary choice | Alternative | Why |
|---|---|---|---|
| Table format | Apache Iceberg | Delta Lake / Hudi | Open, multi-engine, time travel, partition evolution, broad vendor support |
| Catalog | Nessie / Polaris / Unity Catalog | Gravitino / Hive Metastore (legacy only) | Git-for-data, multi-table transactions, fine-grained RBAC/ABAC |
| SQL engine | Trino / Starburst | Dremio / Spark SQL / DuckDB (local) | Native federation, cost-based optimizer, connector ecosystem, Kubernetes native |
| Streaming / CDC | Kafka / Redpanda + Debezium + Flink SQL | RisingWave / Materialize | Maturity, exactly-once, streaming SQL, native Iceberg sink |
| Orchestration | Dagster / Airflow 2.9+ | Prefect / Temporal | Asset-based, data contracts, partitioning, CI/CD friendly |
| Quality / Contracts | Great Expectations / Soda Core + dbt contracts | Data Contracts CLI / Pydantic | Tests as code, CI integration, alerting |
| Semantic layer | Cube.dev / dbt Semantic Layer | AtScale / Kyvos | Headless BI, GraphQL/REST/SQL API, multi-tenant, smart caching |
| Vector Store | pgvector / Qdrant / Milvus | Weaviate / Chroma / Pinecone | pgvector simplifies the stack with PostgreSQL; Qdrant/Milvus for scale >100M vectors |
| LLM inference | vLLM / Ollama / TGI (self-hosted) + OpenAI/Anthropic/Vertex/Bedrock APIs | Lambda / RunPod / Together | Data control, fixed cost, predictable latency; hybrid for peaks |
| Agent framework | LangGraph / CrewAI / AutoGen / Semantic Kernel | LlamaIndex Agents / Haystack | Stateful graphs, human-in-the-loop, tool calling, multi-agent orchestration |
| Observability | OpenTelemetry + Grafana + Loki + Tempo | — | End-to-end traceability of flows and agents |
Conclusion
Apache Hadoop fulfilled its mission: it was the standard that democratised big data processing. But it was born for a world of batch and immobile data, not for feeding AI agents that decide and act in milliseconds. Keeping it today means burning budget on “keeping the lights on” while competitors serve features to their models in hours.
The way out is not a big bang, but an incremental migration by domains towards an open lakehouse on Kubernetes, with real-time CDC, data contracts and AI agents consuming governed data. It is a proven path with measurable ROI, without stopping the business.
At BAOSS we have modernised six enterprise clusters with this pattern, cutting data lead time from days to hours and reducing total cost by between 40% and 55%. If your Hadoop is dead weight, let’s talk.
Request your data modernisation diagnosis and discover the ROI of leaving Hadoop →
Prefer to talk to us directly? Contact the BAOSS team and tell us about your challenge.