
Why “Applying AI” to Your Broken Processes Just Makes the Garbage Go Faster
There is a mantra repeated at every tech conference and in every board meeting: “we need to apply AI”. Companies of all sizes buy thousands of coding-assistant licences. They also commit tens of millions of euros to token consumption and organise internal training sessions over video call. And yet, productivity barely moves. Why? Because the vast majority of organisations are doing exactly what they did with computing three decades ago: applying technology on top of processes that were already broken. In other words, they layer something new over what was already broken. Consequently, the result is simply faster garbage. That is why AI process reengineering must come before any licence or pilot.
That is the story, with data, of a thread circulating these days on X by Vas (@vasuman). He is the CEO of the American AI adoption firm Varick Agents. After speaking with more than 300 CEOs, CIOs and CFOs of the largest companies on the planet, his conclusion is damning. The world has spent a fortune on AI. And yet, for most companies almost nothing has changed. The problem may not be the technology, but the fact that nobody in the chain owns the process. In this article we break it down: why adoption fails and what history says. Then we will look at how to avoid it with a methodology we practice every day at BAOSS.
The 1990 lesson nobody wanted to learn
In 1990, Michael Hammer — an MIT computer science professor — published an article in the Harvard Business Review. It is practically a prophecy. After spending years inside companies that had spent enormous sums on computers with little return, he wrote:
“Heavy investments in information technology have delivered disappointing results, largely because companies tend to use technology to mechanise old ways of doing things. They leave existing processes intact and use computers simply to speed them up.”
If you replace “information technology” with “AI”, you could publish that quote tomorrow. It would fit on the front page of any business newspaper. Hammer also coined a vivid expression: “don’t pave the cowpaths”. In other words, stop automating and cementing an inefficient process. Better still, redesign the process so it works the way it should. Thirty-six years have passed and we are still paving cowpaths.
The figure that explains it all: $1 trillion vs $37 billion
The scale of the mismatch is abysmal. In 2025 companies have spent more than a trillion dollars in capex building AI infrastructure. Microsoft, Alphabet, Amazon and Meta alone exceeded $410 billion. Yet companies have spent only $37 billion actually using it. The tip of the iceberg is the UK Department for Business and Trade’s trial of Microsoft 365 Copilot.
The result, published with complete honesty, was disappointing. They deployed 1,000 licences for 3 months, and the average was just 1.14 Copilot actions per user per day. PowerPoint presentations took 7 minutes less (18 down to 11), but at half the quality. Excel analysis, meanwhile, was completed more slowly, and the time saved on email was, verbatim, “extremely small”. Their literal conclusion: “We found no robust evidence that time savings are translating into productivity improvements”. Even so, 72% of users said they were satisfied or very satisfied.
Ethan Mollick is a Wharton professor and well-known AI researcher. He sums it up in one sentence: “AI use that improves individual performance does not naturally translate into improving organisational performance”. People enjoy the tool, but produce exactly the same output as before.
The number that changes everything: 22 days of process, 17 minutes of work
Hammer’s best figure comes from an insurer he studied. An insurance application took 22 days to travel through the company. Of those 22 days, the total time anyone actually worked on it was 17 minutes. Now calculate what happens if today your “AI expert” deploys the best model in the world on top of that process. Then imagine every individual step becomes twice as fast: they have saved eight and a half minutes. They will sell it as a “50% saving”, collect their bonus and move on. But it is eight minutes.
The savings were never in working on the application, but in the queues and handoffs. Think of the waiting on other teams, the dead time before the second review, and the intervals between departments. Speeding up the 17 minutes is worse than doing nothing. After all, you have spent the budget and proved to the board that “AI doesn’t work”.
You might think this is a relic of the 1990s. It is not. Vas recounts working with a company whose own system logs showed the same phenomenon. Opening a new customer case required 25 minutes of real work. However, the elapsed time from case intake to activation ranged from 2 days to 2 weeks. Work can take minutes while the process still takes weeks.
The fatal temptation: “let’s unify the systems first”
When the data is a mess and systems don’t talk to each other, the instinct is to fix that before touching anything else. People say: “we need one ERP, one CRM, one data platform, and then AI on top”. It sounds good in theory. Nevertheless, any IT specialist knows it is never that simple. The examples of high-profile system-migration failures are legion.
TSB and Zimmer Biomet: the failures that made the news
TSB spent £318 million on a core banking migration. It then swallowed roughly another £200 million in incident costs. The FCA and PRA fined it £48.65 million in December 2022. And it left 5.2 million customers without banking service. Then comes Zimmer Biomet, an $8 billion manufacturer. In September 2025 it filed a $172 million claim against Deloitte. A failed “migration and consolidation” had prevented them from performing basic functions: shipping their product, invoicing their customers or generating sales reports. And those are only the cases that made the news.
The key insight is that you don’t need one system, you need one process. Deterministic integrations broke the moment two systems disagreed about what a vendor record looked like. AI agents, by contrast, tolerate that inconsistency. An orchestration layer sitting on top of the systems you already have is the solution to disparate systems. Your systems don’t just need to talk to each other. They also need to be “happily married”, tolerating each other’s flaws.
The AI process reengineering method: map, sort and measure
To redesign your business you first have to understand it. And that understanding is not achieved by picking a single workflow and spending eight weeks perfecting it. Chances are an upstream sibling process will block it, and you will end up with zero net ROI. Nor can you ingest the whole business in one go. Therefore, the answer is to start at the department level. Without that analytical foundation, it is impossible to close the AI productivity gap.
For each flow, map seven details
Pick a department (finance, procurement, operations) and identify the “clusters” of flows that feed it. For example, in Finance: accounts payable, accounts receivable, FP&A, billing, treasury, reconciliations. Then map seven details for each flow:
The three buckets of every process step
- The happy path: what this flow is responsible for and what happens in the ideal scenario.
- The exceptions: what percentage of the volume leaves the happy path, where it goes and who it involves. Note also the cycle time to resolve it and how much an error here costs.
- What sits upstream and downstream: how the flow interacts with the others when things are delayed or fail.
- The systems of record: which ones are involved, and which one wins when two of them contradict each other.
- How it varies by region, entity, subsidiary or acquisition it comes from.
- Touch time vs elapsed time, and how that gap varies at each step.
- Each person’s AI capability within the function and how much ownership they should have over the future system.
Extracting that information takes two complementary procedures. On the one hand, run process mining against the systems of record to obtain actions, timestamps, throughput, edits and the reality that doesn’t match the documentation. On the other, hold interviews with the operators. After all, the reality of your organisation lives in the heads of 10-20 people who have spent years doing that exact work for your exact company. And your AI, to work, has to be adopted by those people. Doing only one of the two leaves you with an incomplete picture.
Agents that work: they are not just calls to an LLM
Process redesign is a sorting exercise. Every process step falls into one of three buckets:
Three buckets: deterministic, agentic and human-in-the-loop
And when deploying them, don’t forget to review the risk of AI agents and how to control it.
- Deterministic. If X then Y, no judgement. For example: if the invoice is under a threshold amount, and it matches the purchase order and the delivery note, it gets paid. These actions are best done as pure software: cheap, auditable, deterministic (it never hallucinates) and fast. You don’t need a sophisticated model call to do what ordinary code can do.
- Agentic. Suppose you have thousands of past examples of humans making a judgement call with the outcome recorded. If the risk is low (deal desk approvals, GL accounting coding), by all means use an LLM for the judgement. Especially if the output is a yes/no, a “route to this team”, a flag/unflag or a match/no-match. Here you judge the difficulty of the action, not of the thinking.
- Human in the loop. For steps that are too risky or lack sufficient historical context, keep the person in the loop. After all, the cost of an agent getting the action wrong is too high. But put all the relevant evidence in front of the human at the moment of decision. For example, the agent detects a discrepancy between an invoice and a purchase order. It then presents the person with 3 options: approve, reject, or give feedback and route it. The agent has saved them 40 minutes of digging through emails and records. So they can decide in 30 seconds.
Once every step is classified, you can turn a 25-step process into a cluster of 3 agents. Add deterministic steps before and after, plus 2 human-in-the-loop checkpoints to unlock. That reengineering work, together with the agents themselves, is where all the ROI lives.
Then, fix the KPI baselines before you build anything. Your goal is to compute the numbers behind the process you are solving, and where and how they are measured today. If you can’t, the project is doomed to fail. In 12 months you need to be able to say “we were at X and now we are at 3X, or 10X”, thanks to the agents. Only then can you call it a success.
The real case: a 12-step bank reconciliation turned into 3
Once again, in practice, what it looks like. Vas and his team reengineered a global company that reconciled more than 300 bank accounts every month. An offshore team handled two-thirds. Two other regions split the rest across three different formats, all in Excel. There were more than 12,000 open reconciliation items. In addition, the team spent 4 days at the start of each month just obtaining statements. Their reconciliation process consumed nearly the entire month, every month.
The previous flow was a pile of waiting. First, the team hunted down and collected statements from each bank in its own format. Then they normalised them into the regional ledger and extracted the accounting statement. Next, they matched line by line and flagged what didn’t match. Then someone would write to a local controller to ask for context, wait for the reply and chase it if it didn’t come. Finally, the team posted the adjustment, consolidated the region and repeated the whole process for the other two regions, each in its own format. If you speed up every step, the matching gets faster. The problem is that matching was never the problem. In fact, the real problem was the 4 days of waiting for statements, the email to a controller in another time zone and the reply that took 3 days.
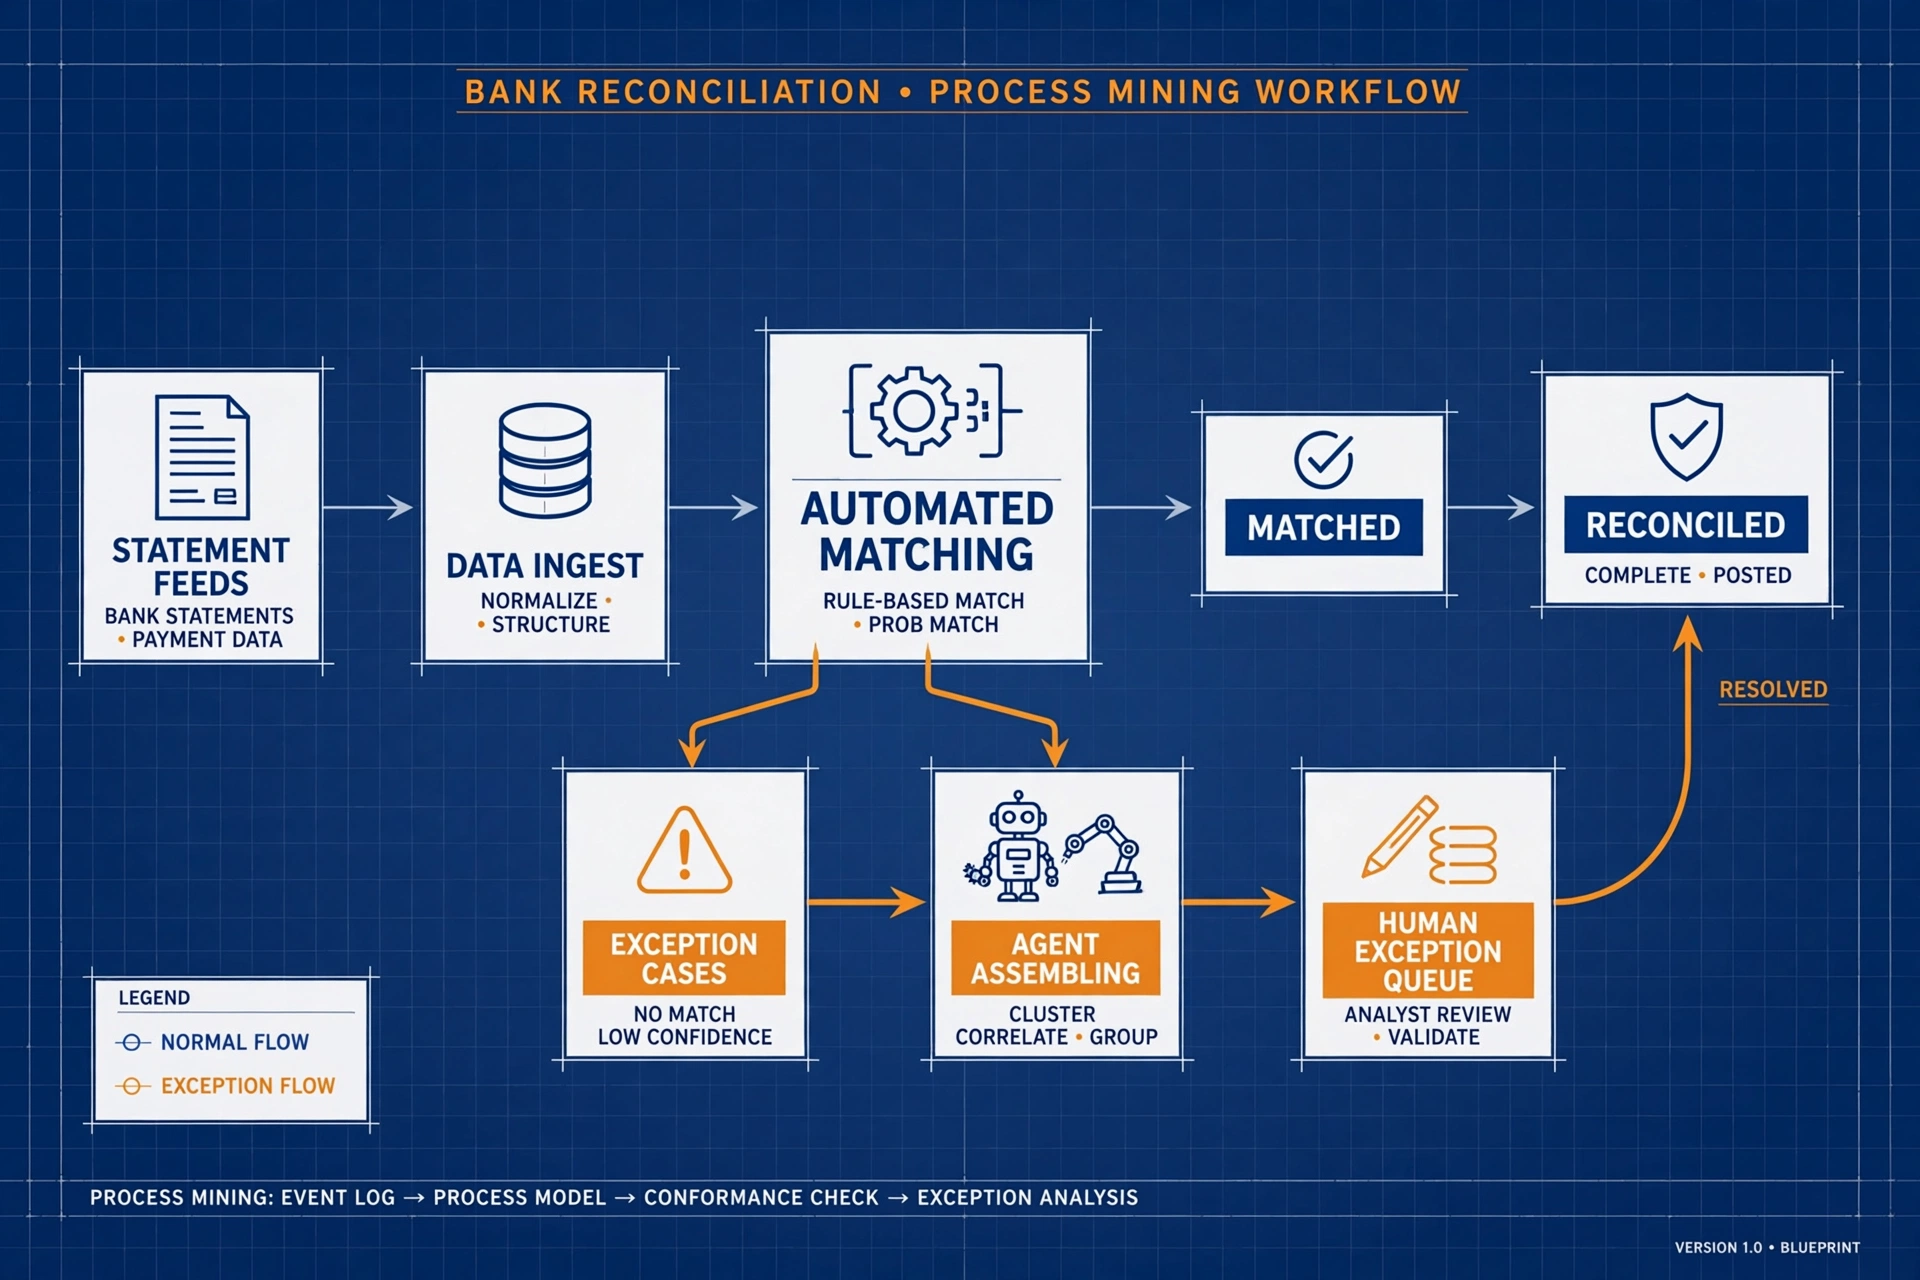
In short, the new process had three steps:
- Statements arrive via a feed, conveyor-belt style, instead of being chased down. This has nothing to do with AI.
- Rules automatically match everything they can. If not, an agent assembles the case end to end. The case arrives with the item itself, historical categorisations, evidence gathered from several systems of record, and a proposed next step.
- Finally, a human works their exception queue with the evidence prepared for review. That replaces manually digging through data scattered across ERPs and spreadsheets.
The searching, the emailing, the waiting, the retyping and the regional consolidations disappeared entirely. That is the difference between an agentic system that saves minutes and hours, and an agentic system that saves weeks.
The results when it is done right
When you approach the work this way, the impact touches the four levers that matter in an AI transformation. They are cost (ideally lower), revenue (ideally higher), time (ideally faster) and risk (ideally lower). Across Varick’s deployments — about half at public companies — this is what moved, lever by lever: The lesson is clear: AI process reengineering is the precondition for any automation that delivers a return.
What moved, lever by lever
- Time. Month-end close went from 18-22 days to 7-9 days. The team now triages supply chain disruptions in under 6 hours, versus several days.
- Revenue. Deals used to sit idle for 23 days on average. Now it is 6 days. In addition, reps’ administrative time dropped from 38% of the week to 14%, and that time went back into selling.
- Cost. Accounts-payable exception handling went from 600-800 invoices a month to fewer than 50. In a marketing organisation, pacing errors had consumed 8% to 12% of media budget and previously only surfaced at month end. Recovering them saved millions per quarter.
- Risk. Payroll corrections fell by 90%, because cross-system reconciliation ran before payroll rather than after. The company’s own policy documents answered 80% of employee support queries, while edge cases still escalated to an HR human.
In total, the value delivered across that set of deployments exceeded $100 million. Moreover, it was co-created and measured together with the clients.
Why it is not more common: interference, risk and the fear of operators
If the method works, why do so few people apply it? For three reasons that are less technological and more human.
Three reasons that are less technological and more human
First, nobody in the chain owns the process. Whoever signs an AI contract today can control the tooling and vendor selection. However, they certainly do not control the process. Nobody with that remit can walk into finance and say their 14-step process should have 5. So nobody does it: you “apply AI” to what you already have and end up with faster garbage. Redesigning a process that spans four departments requires someone able to tell all four that the process is changing. Very few people in a company can do that. Therefore, it has to come from the top.
Second, AI is perceived as risky. The status quo is “safe” for most. Nobody gets promoted because the AI works, but you can get fired if it doesn’t. Meanwhile, clinging to the status quo means letting the company die slowly.
Third, the people doing the work today have to want the new system. The accounts-payable lead and the finance analysts have to adopt it and champion it tomorrow. And they have to disclose information they believe could replace them, even though in most cases it won’t. When Hammer tried to eliminate a handoff in the 1990s, that meant firing the person whose job was that handoff. Then it meant asking everyone else to change the way they worked, while the “software” of the day could not support that change. That is why, when the consultants left, the structure and the process snapped back to their original state: full of inefficiencies and errors.
Today two things are fundamentally different. First, native AI tools offer an incredibly fluid state of software that adapts to change. An agent installed in your system of record can execute handoffs that used to depend on people. It can also handle the discrepancies of deterministic software at the same time, and it is immune to the variance typical of humans. Second, the work that gets eliminated first is almost entirely coordination: chasing, waiting, escalating, triaging. After those improvements and a real AI transformation, what remains is high-judgement, high-leverage work. Which is exactly what your best people should be spending all their time on anyway.
The single-vendor trap
Traditional consultancies are decent at process work, to be fair. For example, if you want an elaborate illustration of a 15-step process spanning 10 countries and 3 entities, they will produce the prettiest PowerPoint you have ever seen for $300,000. What they don’t know how to do is the other half, the more important one. They don’t know what can be trusted to a model, how much an agent running 40,000 times a month costs, or which model to use for which type of task. Nor do they know how to design an optimal evaluation set, or which of the three buckets each step falls into. Consequently, your redesign is created by consultants who are guessing.
AI labs, by contrast, have the opposite problem. They can build an agent, but they have never sat down with finance and operations. They have never taken apart a flow where both departments argue over who owns what and who is upstream of whom. So they slap AI onto a broken process and call it “automated”, instead of gutting it and redesigning it.
Moreover, the biggest “applied AI” labs will force you to marry their models forever. Betting your company’s entire intelligence embedding on a single vendor is suicide. Tomorrow they can throttle the rate, quantise, raise prices or retire the model you run on. Then you are left with the mess and the bill. Switching the endpoint from Claude to Gemini or DeepSeek is not as simple as it looks. Re-running the evaluations and re-deciding which level of reasoning to use per call is a laborious process, and the labs are not going to help you.
What you need is the best of both worlds combined. You need people who have genuinely run a finance, operations, sales or HR function. You also need engineering capable of shipping production software into ERPs and CRMs. Finally, you need AI engineers capable of building vendor-neutral scaffolds with governance and evaluation sets built in. What you keep needing is the team having the process owner, the software engineers and the AI engineers in the same room inside the project. Yet almost nobody has all three.
Conclusion
The lesson of this thread is as old as it is current: technology never replaced a bad process. Instead, it accelerated it. The wasted time was not in the work itself, but in the queues and the handoffs. Before buying thousands of AI assistant licences, ask yourself which process you are going to redesign and who has the authority to change it. Start with one department. Then run process mining and interview the operators. Then classify every step as deterministic, agentic or human-in-the-loop, measure the baselines, and only then build.
At BAOSS we have been applying this same discipline for years. We help companies redesign processes before automating them, with solid AI agents, governance and ROI measurement from day one. We don’t sell “applying AI”; we sell transformation that gets measured. If you are at that point, let’s talk about how to start.
Article inspired by the thread by Vas (@vasuman, CEO of Varick Agents), “AI Adoption Without Process Change” (September 2026). The figures cited come from public sources. They are: Harvard Business Review 1990, the UK government’s Copilot trial, the TSB and Zimmer Biomet cases, and published metrics from Varick’s deployments.
Prefer to talk to us directly? Contact the BAOSS team and tell us about your challenge.